Enterprise LLM Integration & Generative AI Solutions for Business
We seamlessly integrate state-of-the-art Large Language Models (LLMs) such as OpenAI GPT-4o, Anthropic Claude, and self-hosted models via RAG pipelines into your enterprise applications. Unlock enterprise knowledge with strict GDPR data governance.
Key Challenges Resolved by LLM Integration
Without tailored digital architectures, manual processes and generic tools quickly create critical bottlenecks.
Privacy & GDPR Data Leakage
Companies rightfully worry that proprietary data or customer secrets will be ingested to train public foundation models without consent.
Hallucinations & Inaccurate Outputs
Generic chatbots hallucinate when disconnected from real-time enterprise documents, PDFs, and SQL databases.
Spiraling Token Costs & High Latency
Unoptimized prompt chains and missing semantic caching inflate token consumption and cause sluggish end-user response times.
Lack of Deep Tool Integration
Isolated AI chat brings minimal ROI if models cannot execute actions directly in ERP, CRM, or operational tools.
Our Enterprise LLM & RAG Solution Architecture
We architect secure, high-performance AI pipelines with zero-data-retention compliance, semantic search, and autonomous tool calling.
Key Capabilities & Architectural Modules
Every module is engineered to your operational scale and maintained with performance-first code.
Enterprise RAG Knowledge Base
Real-time indexing of technical documentation, contracts, and PDFs with semantic embeddings and verifiable citations.
Multi-Model Orchestration
Dynamic routing between GPT-4o, Claude 3.5 Sonnet, and lightweight models for optimized cost-per-query benchmarks.
PII Masking & Privacy Shield
Automated redaction of sensitive identifiers, banking info, and personal records prior to model ingestion.
Semantic Vector Caching
Frequently recurring queries are resolved instantly via Redis vector caches with sub-100ms latency.
Function Calling & API Tool Use
Enables LLMs to query live SQL schemas, file tickets in Jira, and generate dynamic transactional documents.
LLM Observability & Monitoring
Real-time auditing of token spend, output quality, latency drift, and human feedback loops using Langfuse.
Tangible Advantages for Your Organization
Clear outcomes: Boosted operational speed, diminished overhead, and heightened customer trust.
80% Faster Knowledge Retrieval
Empower staff to extract precise operational insights from thousands of internal documents in seconds.
100% GDPR & Data Governance
Zero data retention agreements guarantee your internal prompts never train third-party foundation models.
60% Lower Operating Overhead
Smart semantic caching and adaptive multi-tier routing drastically curb monthly token expenditures.
Zero Vendor Lock-in
Decoupled architecture allows hot-swapping between OpenAI, Anthropic, or local open-weights models effortlessly.
From Discovery to Production Launch
Our 5-phase execution model ensures predictable roadmaps, punctual milestones, and fixed budgets.
Use Case & Security Audit
Analysis of internal data assets, compliance parameters, and technical evaluation of business impact.
Vector Pipeline & Ingestion
Document parsing, semantic chunking, embedding generation, and vector database ingestion.
Prompt Architecture & Tool Calling
Engineering tailored system instructions, few-shot examples, and reliable function-calling APIs.
UI Integration & Guardrails
Crafting modern Next.js client interfaces or deep webhook connectors into Slack, MS Teams, and ERP portals.
Deployment & Observability
Stress testing, user onboarding, latency benchmarking, and automated telemetry tracking via Langfuse.
Industries & Teams That Genuinely Benefit
Engineered around specific real-world operational challenges for maximal market impact.
Intelligent Contract & Document Audit
Automated analysis of hundreds of contracts for liability terms, compliance clauses, and deadlines in seconds.
Field Technician Service Copilot
Field personnel query thousands of technical schematics and manuals on-site to resolve machinery breakdowns faster.
Autonomous Product Advisor & Order Support
AI answers complex technical product inquiries, queries live inventory, and assists checkout with zero wait times.
Verified Client Projects Delivered
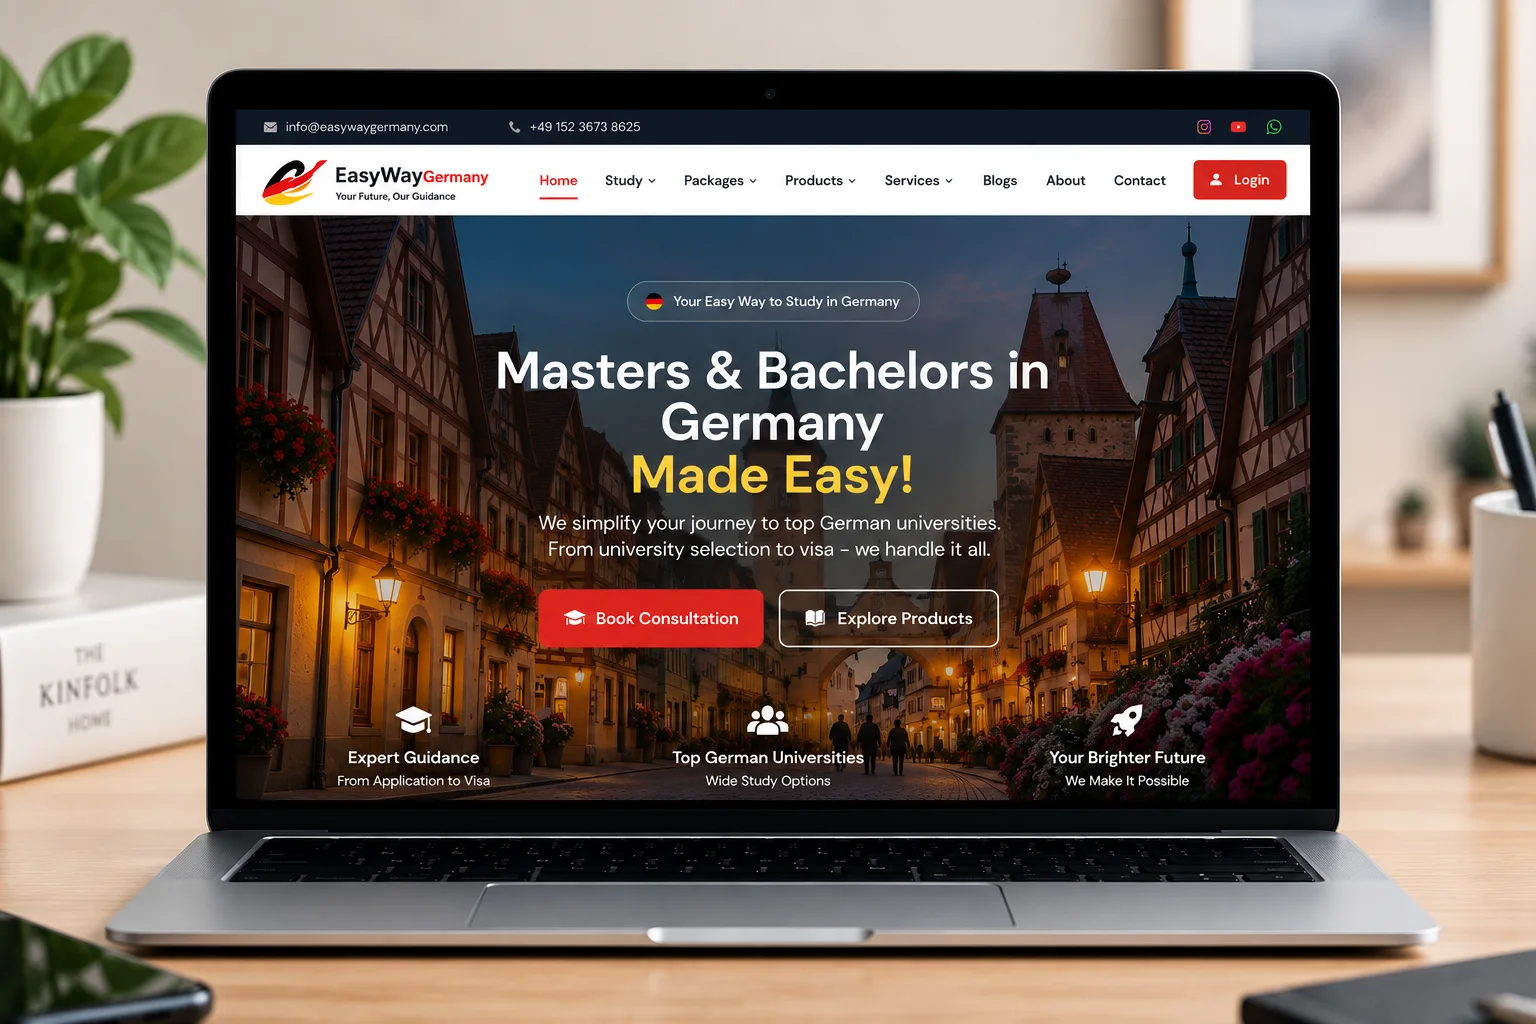
A study-in-Germany consultancy guiding students through admissions.
Related Technical Guides
FAQ on LLM Integration
Transparent answers to the most critical technical and operational questions regarding your project.
Ready to Launch Your LLM Integration Project?
Consult directly with our software architects. We analyze your requirements and deliver a transparent fixed-price roadmap and timeline estimate within 24 hours.